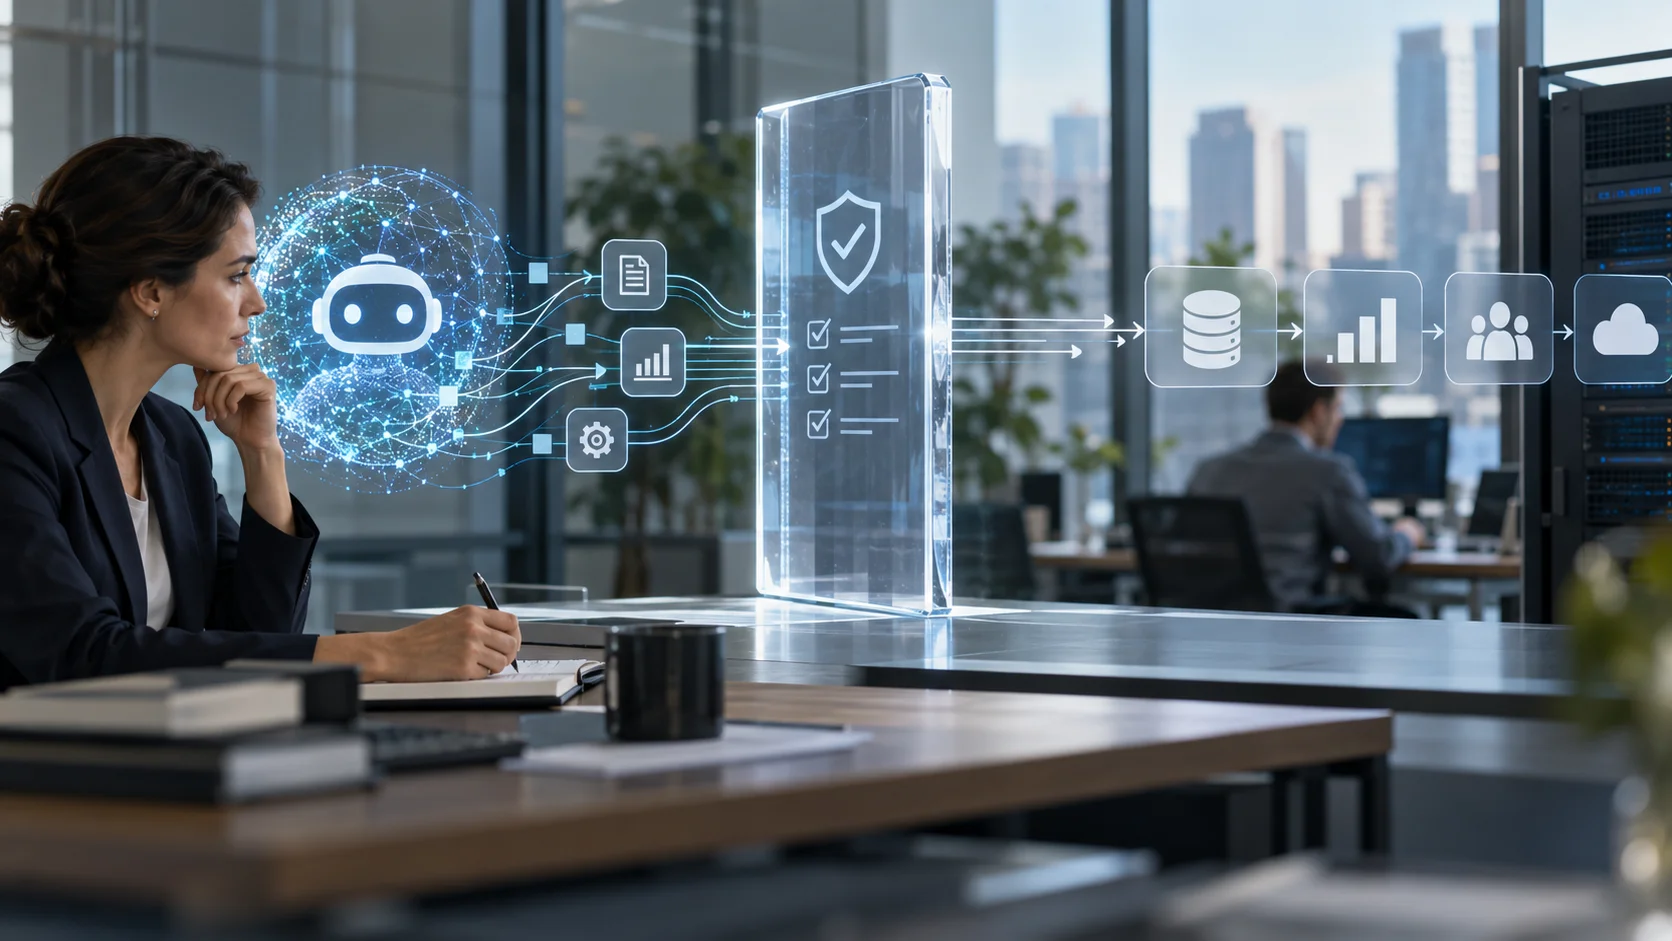
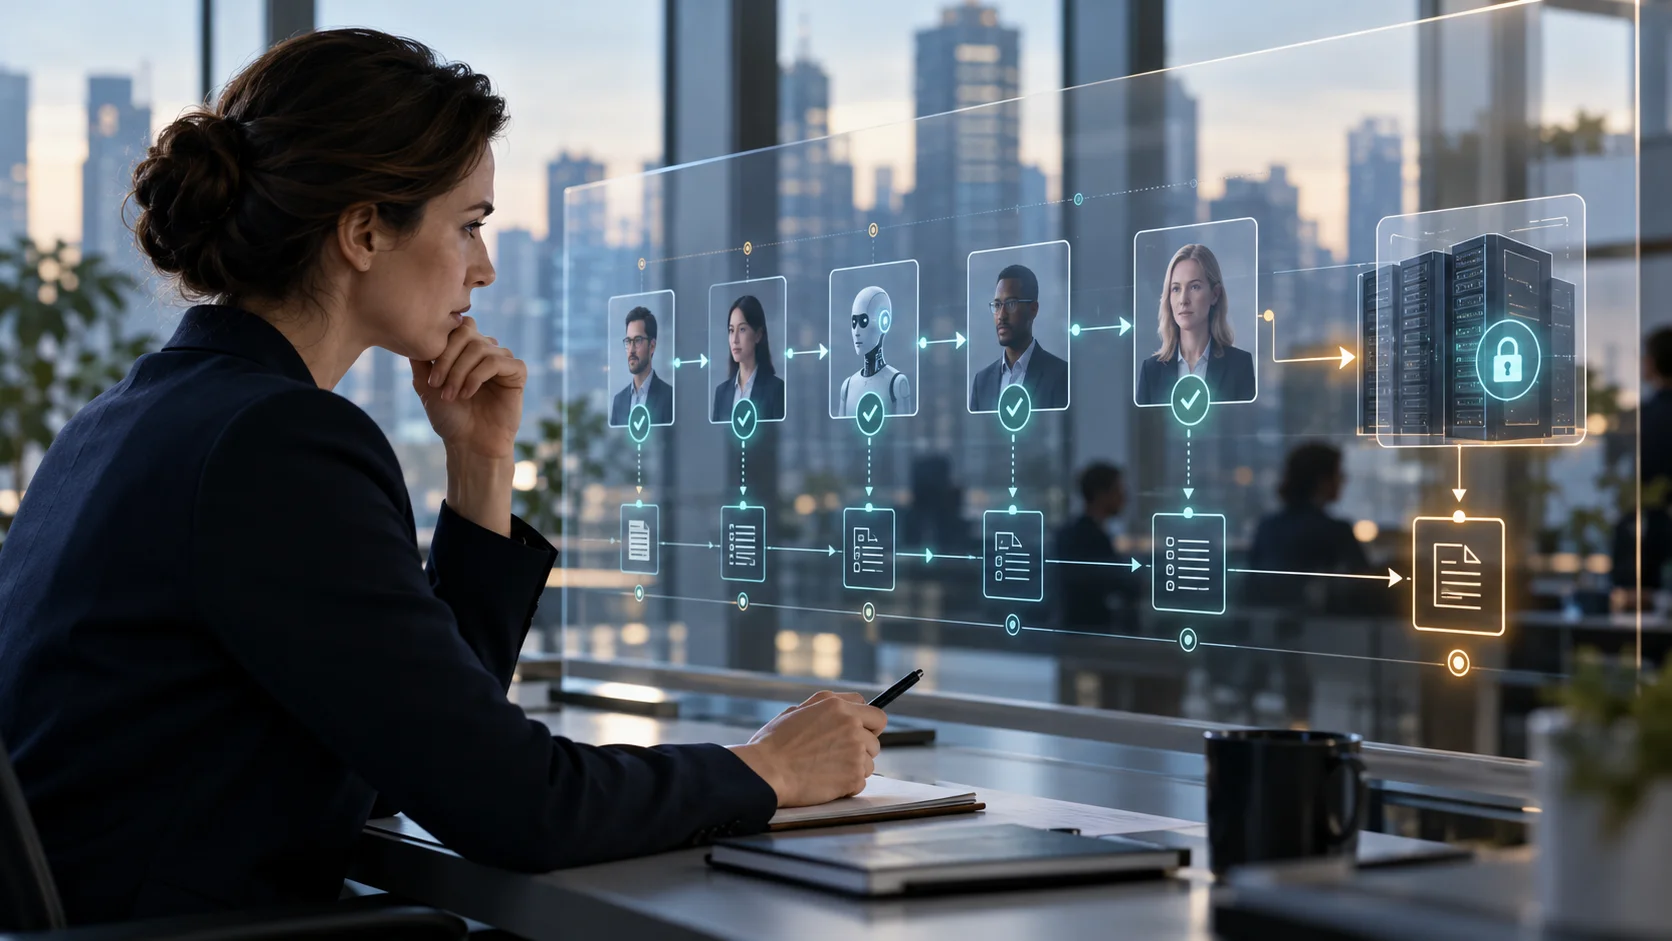
If you collect time-stamped and cryptographically signed evidence used to drive the decision that was made by the agent, you can prove that your agent did not discriminate. In most cases, that data is spread throughout multiple systems, making it a scavenger hunt, with Trustabl.ai it is all centralized and available.
Post 6 of a series on AI liability for general counsels interested in the legal liability associated with building and using agents.
A regulator asks how your agent decided who received the loan offer, the job interview, the insurance rate, or the medical prior authorization. Or a plaintiff asks why the agent denied the claim. Or an auditor asks whether the agent was even allowed to touch protected health information in the first place. The answer “the model said so” doesn’t work. The answer “we have a policy somewhere” doesn’t work either. They want to see what the agent was permitted to do, what it actually did, and that the permission and the action did not discriminate on race, sex, or other protected characteristics.
The EU AI Act, HIPAA, HITECH, and a growing set of US and international rules on automated decision-making all point at the same requirement. You must be able to explain the system’s decisions. Explanation here does not mean pointing to a model, or a narrative about training data. It means a record of the ceilings that were in force, the data classes the agent was allowed to touch, the tools it was allowed to call, the points at which a human had to approve, and the traces of what actually happened under those rules. Proactive proof is the only posture that survives.
Most companies can describe their intentions. Fewer can show the effective permission for a specific run. The content-safety threshold lives in one console. The data-class restriction lives in another. The identity the agent represented lives in a third. The human approval, if it happened, lives in a ticket. When the question arrives, someone has to stitch those pieces together and hope the stitch holds. The stitch does not hold under cross-examination or under an audit.
Discrimination exposure and ordinary regulatory exposure are tied at the hip. An agent that can see protected characteristics, or proxies for them, and can also take an adverse action creates the risk. An agent that can read protected health information and write to a system that leaves the organization creates a different risk under the same evidence standard. In both cases the control that matters is the same: a published set of acceptance criteria that defines what data may be touched, what actions require approval, and what must be masked or blocked, compiled into a contract the runtime enforces, and observed so the record exists before anyone asks.
The practical requirements are clear. You need data-class rules that treat protected characteristics and protected health information as restricted. You need explicit masking or denial before those fields reach a model or a tool. You need human approval on adverse or irreversible decisions. You need the intersection of those ceilings with every other constraint compiled into one signed contract for the agent version. You need traces that record the data classes touched, the policy decisions made, the approvals given, and the policy version that was in force. You need an inventory that maps those controls to the regulation so the package can be handed over without a scavenger hunt.
At Trustabl we treat explainability and non-discrimination evidence as an output of the same acceptance criteria that limit other liability. Company Policy can declare protected classes and protected health information as restricted, require masking, and require human approval on adverse actions. The compiler intersects those requirements with the other ceilings and produces one signed contract. It generates the corresponding policies for the Policy Enforcement Points (PEPs) so the restriction holds at runtime instead of living only in a document. The Safe Agent Control Plane records the data classes, the decisions, and the approvals in the same evidence bundle. The open-source Safe Agent Builder tools help teams produce agents that can actually meet those criteria. We do not claim this proves the absence of bias in the underlying model. We claim it proves what the agent was allowed to do and what it did under rules the organization set, which is the question regulators and plaintiffs actually ask.
Companies will continue using agents to decide, recommend, and filter. The companies that can show the decision was made inside published, enforced ceilings will be in a different position from the companies that can only describe what they hoped the agent would do.
Additional reading in this series
Related Blogs
Agent Reliability Resources