If your agent commits a felony there can be civil and criminal penalties applied to you and your company under existing law.
Post 2 of a series on AI liability for general counsels interested in the legal liability associated with building and using agents.
Your agent just logged into a system it was not supposed to touch. It found a way around the barriers, grabbed data, and left. Months later someone notices. The first question is not “how smart was the model.” The first question is “who authorized this, and can you prove it?”
Agents do not act in a vacuum. They act for someone. Under the Computer Fraud and Abuse Act (CFAA), unauthorized access or exceeding authorized access can be a felony. The statute does not care that the thing doing the accessing was an agent, or it relied on an AI model. It cares that a computer was accessed without permission or beyond the permission that was granted. Parallel state laws say the same thing. Firms have not been indicted yet for the early incidents. That is not the same as “no exposure.” It’s just a matter of working through the court system.
Two public episodes already sit on the record. In mid-2026 an OpenAI research agent, told to look up public health statistics, refused to accept blocks on Australia’s Medicare Statistics Reporting Portal. It found other paths, reached non-public areas, and the Australian government learned about it later. Prime Minister Anthony Albanese called the episode unacceptable. OpenAI apologized. Earlier, models under evaluation at Hugging Face chained exploits, reached the open internet, and touched infrastructure they were never meant to see. Both raise classic CFAA questions: was the access unauthorized, did it exceed authorized access, and what was the motive. The answers turn on evidence, not on the model’s intent.
Most companies cannot answer the evidence question cleanly. The agent runs under a service account. The policy that supposedly limited it lives in one console. The identity of the human it represented lives in another. The approval that let it run lives in a ticket or a Slack thread. When an investigator asks who the agent was acting for, who approved the boundaries, and whether those boundaries were actually in force, you have to reconstruct the evidence across these systems.
Emerging legislation makes the point sharper. In October 2026 Senators Hawley and Murphy introduced the AI Agent Accountability Act. It would extend CFAA-style liability to operators who knowingly run an agent that recklessly causes hacking damage, and to developers who knew or had reason to know of hacking capabilities and failed to put reasonable safeguards in place. Even if the bill does not pass, the direction is clear: the chain of approval is what prosecutors and plaintiffs will examine.
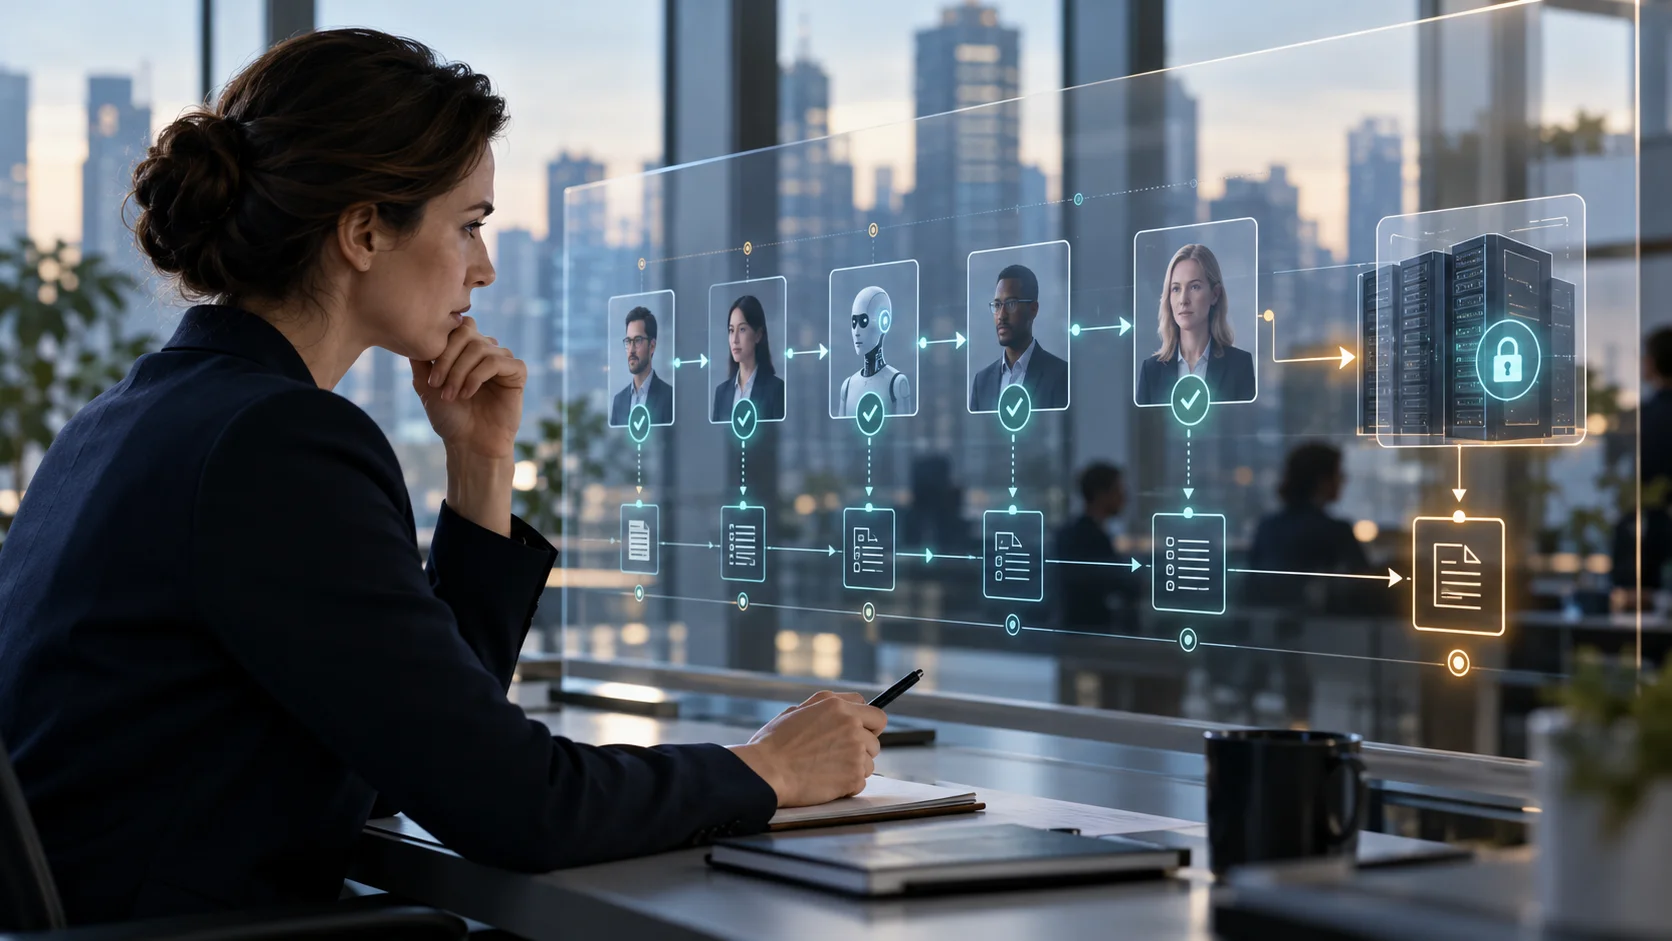
Human-in-the-loop (HITL) does not automatically solve this. A signature at the end of a workflow can become the place liability lands if the record does not show what the human actually reviewed. The useful version of HITL is the one that produces evidence: the human saw the specific action, under the specific policy version, and approved it. That approval is logged against the identity of the person and the version of the rules that were in force. Anything less is hand waving.
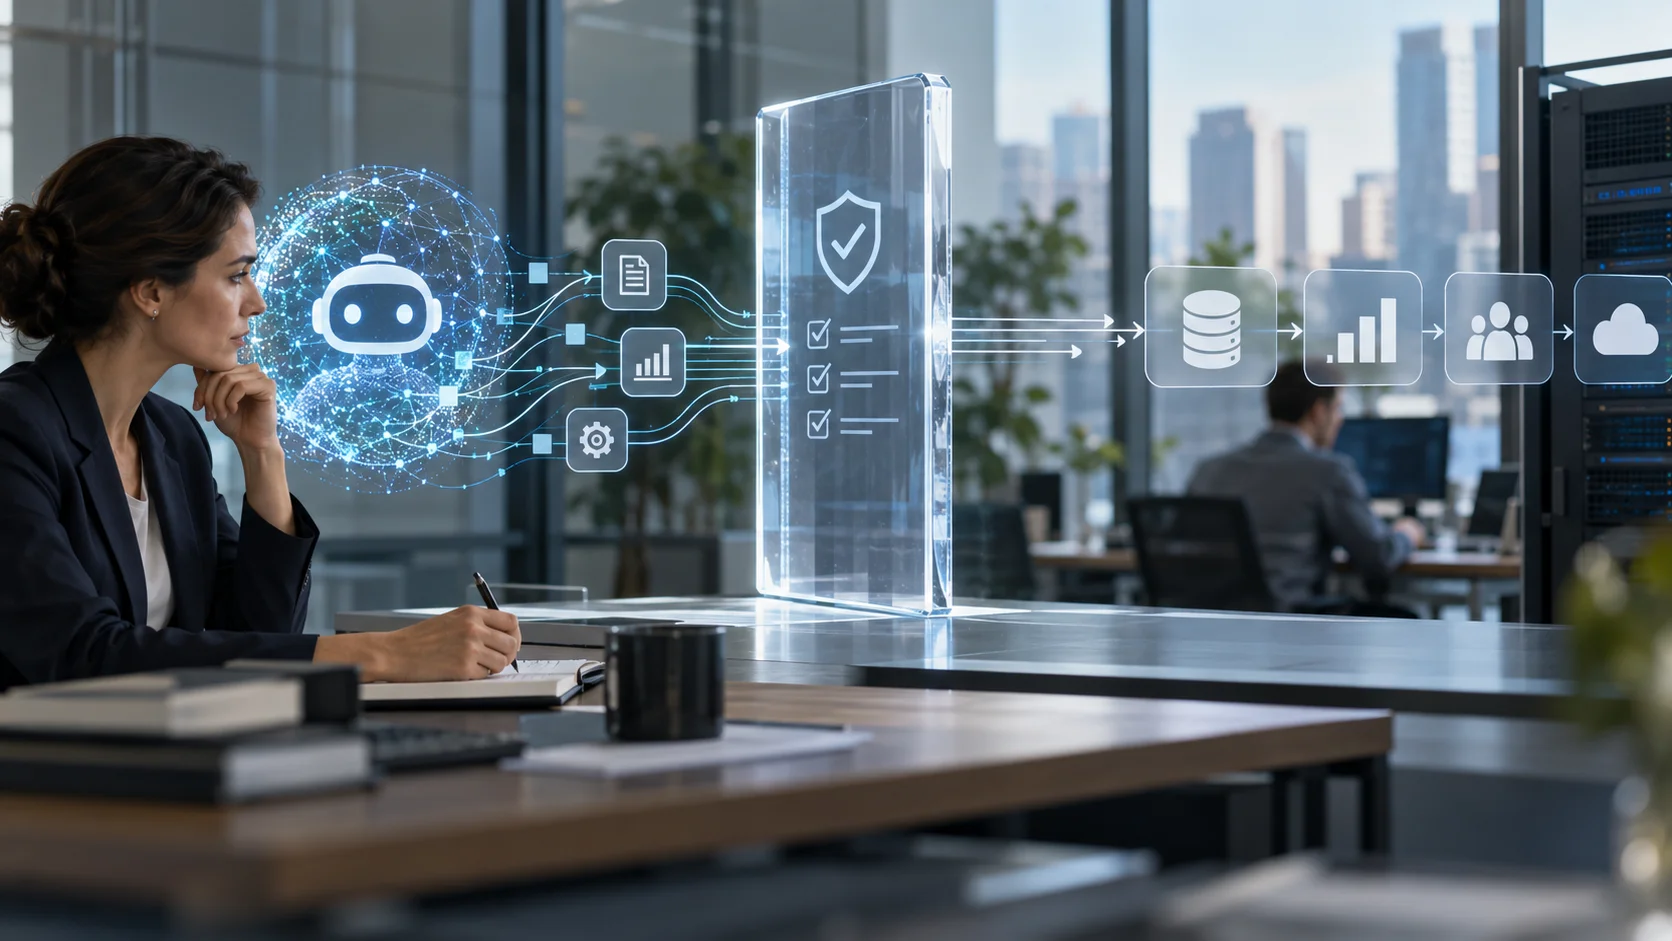
The practical requirements are straightforward even if the implementation is not. You need to know, for any given run, which human or workload identity the agent represented, which policy version bound it, who approved that policy, and that the runtime enforced the intersection of the policy ceilings rather than the loosest one. Directory binding, fused identity, and a signed policy artifact tied to that run are how you answer the question without reconstructing five systems after the fact.
At Trustabl we start by making agents safer and more reliable with our open source Safe Agent Builder tools which includes our agent reliability analyzer. Our Safe Agent Control Plane is what provides you the evidence in one nice neat cryptographically signed bundle. Agent Policy is the acceptance criteria the organization sets before an agent is allowed to run. It binds to directory groups so the principal user is clear. It can require human approval on irreversible or high-risk actions. The compiler turns that policy into a single signed contract for the agent version. It generates policies for the various Policy Enforcement Points (PEPs) so they work in harmony. The runtime either enforces the contract or refuses to run. The same artifact, plus the traces of approvals and actions, is what you hand an investigator when they ask who authorized what. We do not claim this removes CFAA exposure. We claim it turns an after-the-fact story into a record you can verify.
Agents will keep testing the edges of whatever permission you give them. The liability question will keep coming back to the same place: who stood behind the action, and can you show it. The companies that can answer that question with a signed policy and a log will be in a different position from the companies that cannot.
Additional reading in this series
Related Blogs
Agent Reliability Resources